Automating Editorial Triage: Routing Drafts Across 13 Properties with Cosmic and TypeSafe
Tony Spiro
September 21, 2026
Draft-only publishing is the right default for any editorial team large enough that no single person sees everything. Nothing reaches the public until an editor approves it. The policy is easy to adopt, and it creates a new problem on day one: every draft now needs a person, and people read in the order things arrive rather than the order that matters.
Drafts can arrive from everywhere. Staff writers, section editors, freelancers filing against a brief, contributors who write for you twice a year, syndicated copy, and increasingly AI tools drafting alongside the team. The volume problem is the same whatever the source, and it shows up long before anyone adopts an agent.
For one team running multiple web properties, that queue stops being readable within a week. Our content governance at scale piece argued the policy. This one builds the mechanism that makes the policy survive volume.
The approach: Cosmic holds the content, the draft state and the roles. A classification model decides which drafts a human actually has to open, and in what order. Below is the architecture, working code against Cosmic's TypeScript SDK and TypeSafe's HTTP API, and the accuracy we measured on a real corpus, including the parts that did not work.
What Jev does, and what it does not do
TypeSafe ships a model called Jev that answers typed questions about a block of text. You send content as state along with a map of questions, and you get structured answers back. There are three question types, documented on their API reference (read September 20, 2026):
-
Noul returns the probability that a yes/no question is yes, as a number from 0 to 1.
-
Choice picks one option from a set you define, and returns the full probability distribution plus a
confidencevalue. -
Score rates content against an ordered rubric you define, from two to ten levels, and also returns
confidence.
Jev generates no prose and writes no code. It classifies and scores. That constraint is what makes it useful here, because editorial triage is mostly a classification job: decide what each draft is, then decide who needs to read it.
The architecture
-
A draft is created in Cosmic by a staff writer, a freelancer filing against a brief, an occasional contributor, a syndication feed, or an agent. The pipeline does not care which.
-
A webhook fires to your route handler.
-
The handler sends the draft body to Jev with every question attached to a single request.
-
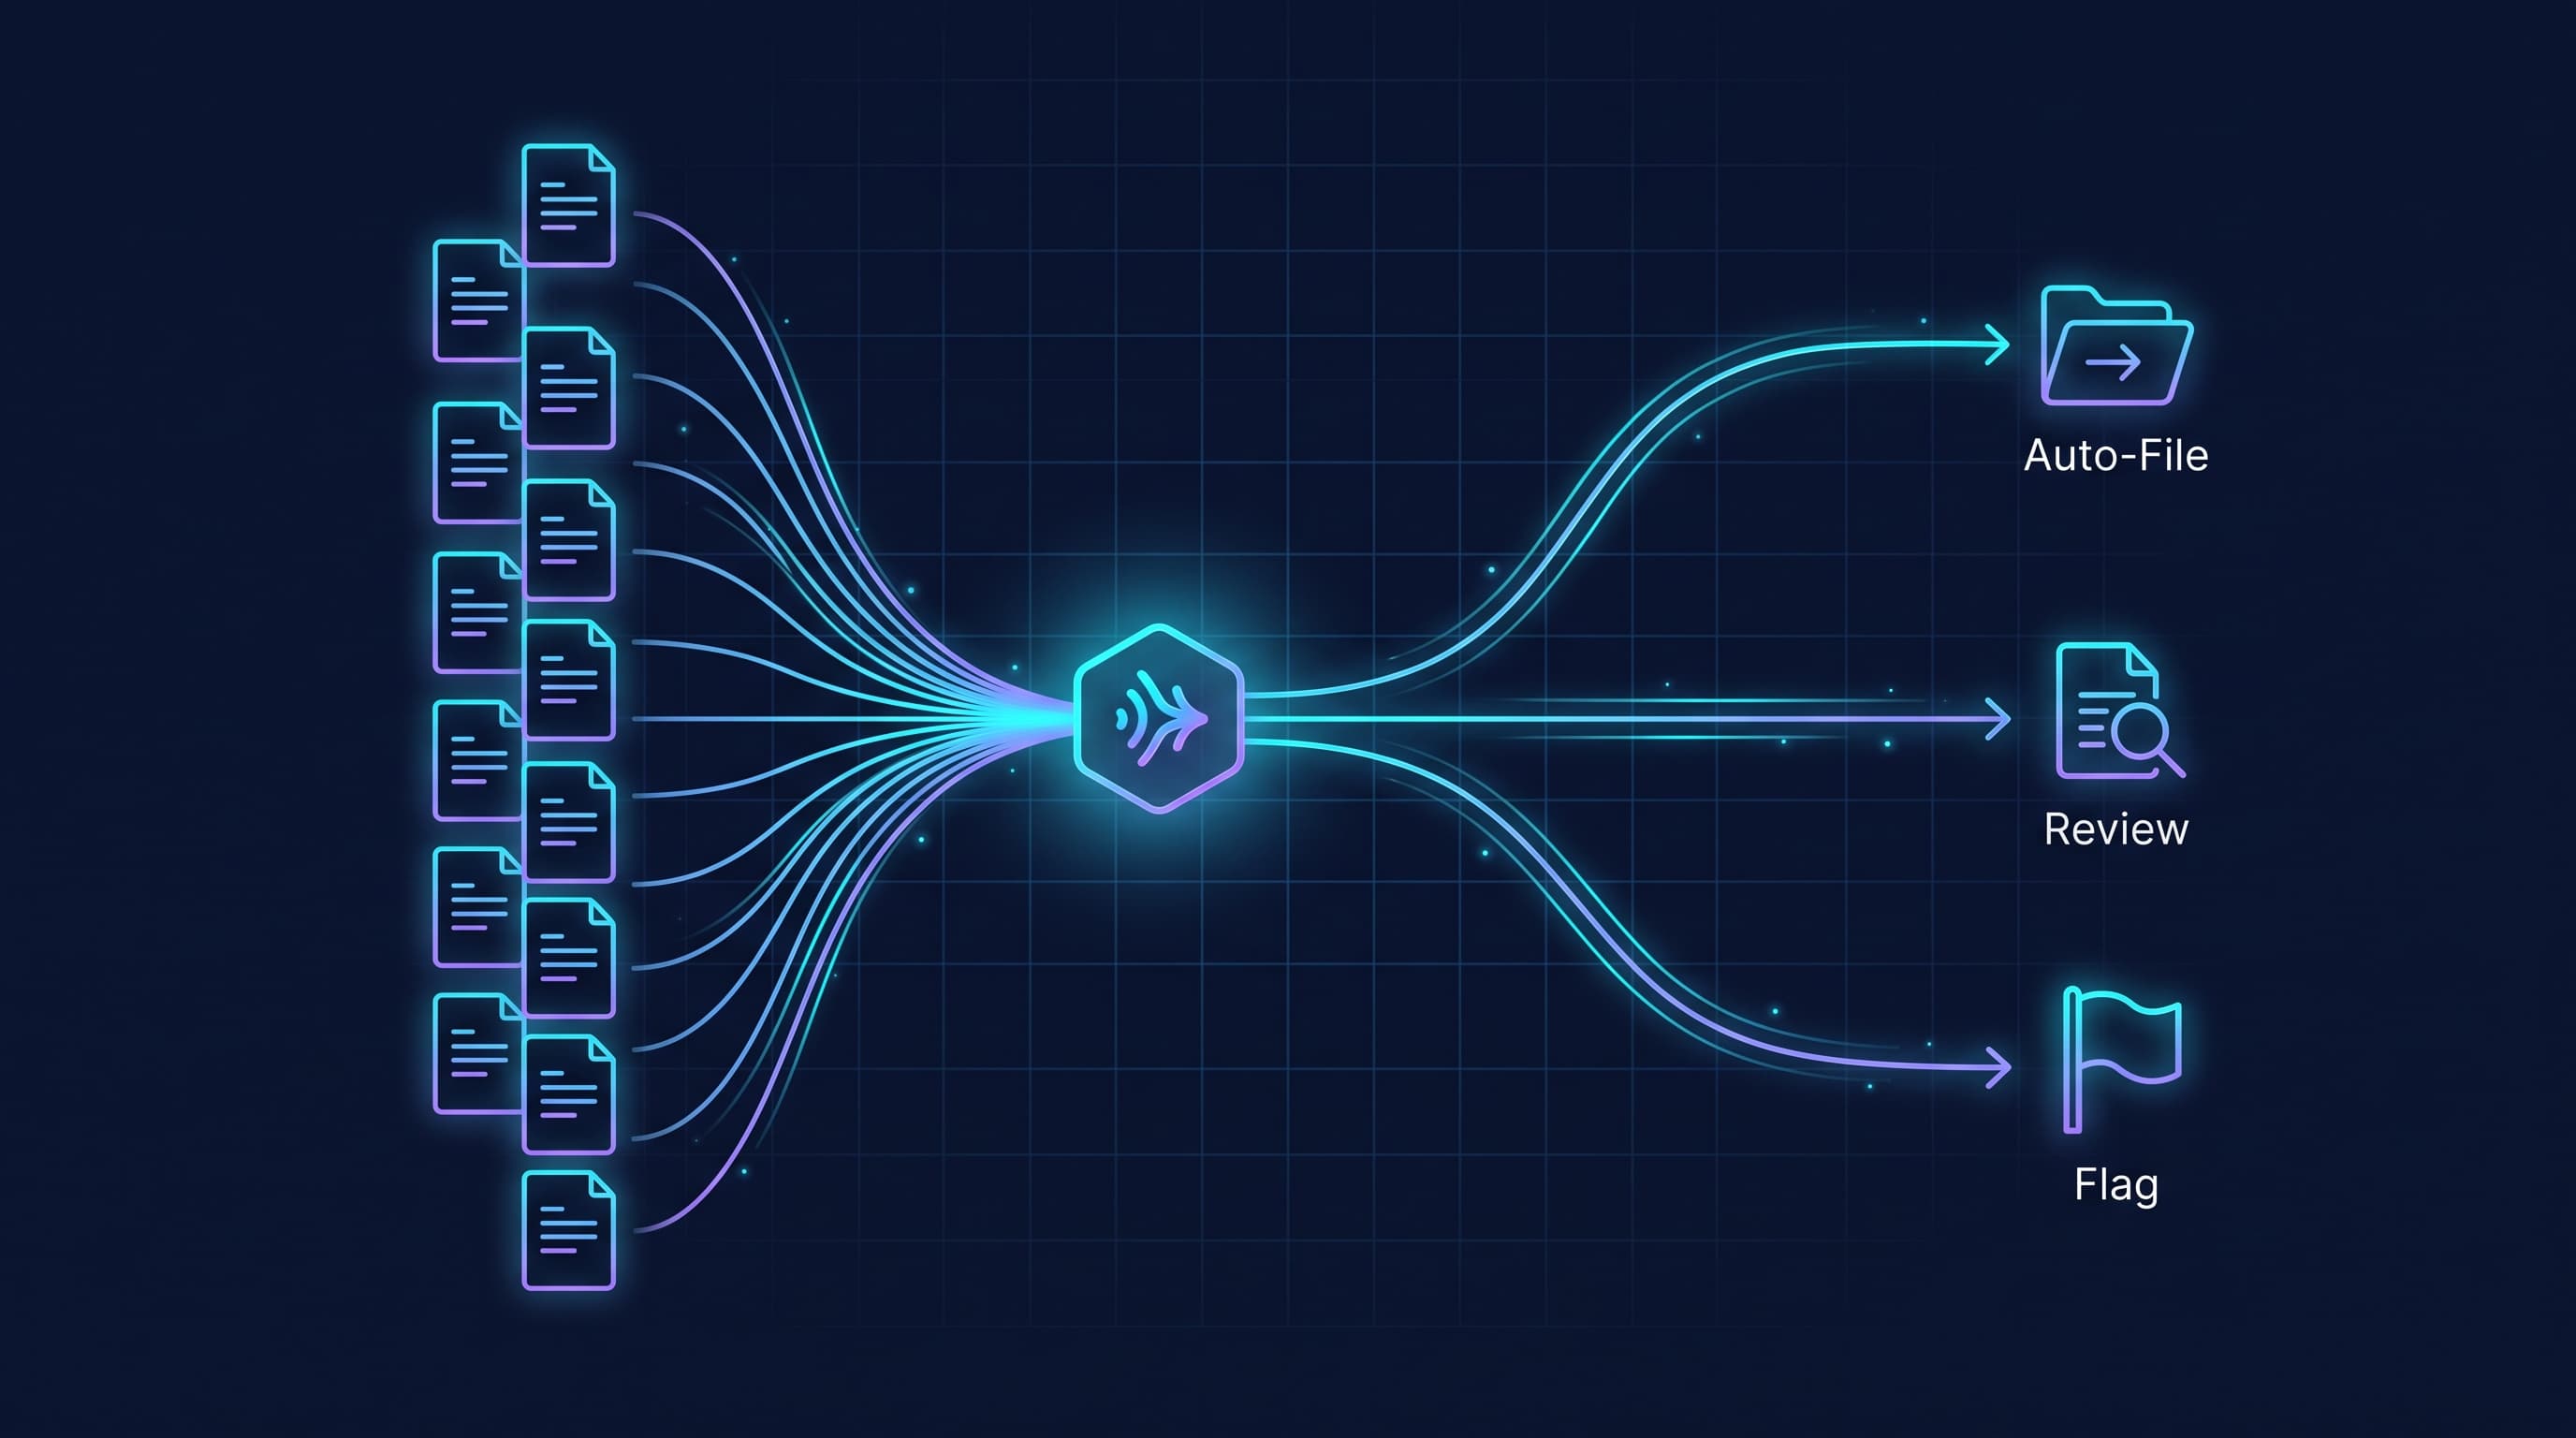
Confidence decides what happens next: high-confidence answers write straight back to the object, low-confidence answers route to a human.
-
The editor opens a queue that is already sorted, categorised and flagged.
The draft never publishes itself. Everything below only decides who looks at it and when.
Step 1: write the questions, and take criteria seriously
This is the part that decides whether the whole thing works. Every question type accepts an optional or required criteria field, and the quality of your criteria matters more than the wording of your instructions.
Here is the question set we ran, targeting a fictional media group with thirteen consumer titles:
{
  "state": "<the draft body>",
  "model": "jev-latest",
  "questions": {
    "property": {
      "type": "choice",
      "instructions": "Which of our titles should publish this draft?",
      "criteria": {
        "switchback": "Cycling: road, gravel, commuting, bike gear and maintenance",
        "field_and_forge": "Outdoor gear: hiking, camping, trail running, packs and footwear",
        "the_marrow": "Food: recipes, technique, restaurants, ingredient deep dives",
        "marrow_dispatch": "The Marrow's newsletter: short, single-subject, first-person food writing",
        "ledger_lane": "Personal finance: saving, borrowing, tax, consumer money decisions"
      }
    },
    "voice_fit": {
      "type": "score",
      "instructions": "Rate how well this matches our editorial voice.",
      "criteria": [
        "Promotional or hyped. Superlatives without evidence, marketing register, reads like copy written to sell.",
        "Flat or generic. Accurate but characterless, could have come from any publication.",
        "Plain, specific and first-hand. Concrete detail, measured claims, an identifiable point of view."
      ]
    },
    "unverified_claim": {
      "type": "noul",
      "instructions": "Does this draft state a factual claim without attributing it to a source?",
      "criteria": {
        "true": "Contains a statistic, price, comparative claim or third-party assertion with no named source.",
        "false": "Every factual claim is attributed, or the piece is explicitly first-hand or opinion."
      }
    },
    "content_type": {
      "type": "choice",
      "instructions": "What kind of piece is this?",
      "criteria": {
        "news_report": "Reports something that happened, with dates, named sources or quotes.",
        "how_to_guide": "Instructional. Steps, technique or maintenance the reader is meant to follow.",
        "product_review": "Assesses named products against criteria and reaches a verdict.",
        "opinion_column": "Argues a position in an identifiable writer's voice.",
        "roundup": "A list of products, places or picks grouped by a theme."
      }
    },
    "undisclosed_promotion": {
      "type": "noul",
      "instructions": "Does this draft promote a product, brand or sponsor without disclosing the relationship?",
      "criteria": {
        "true": "Promotional intent with no visible disclosure of sponsorship, gifting or affiliate links.",
        "false": "Either no promotional intent, or the relationship is disclosed in the draft."
      }
    },
    "structural_completeness": {
      "type": "score",
      "instructions": "Rate how complete this draft is as a finished piece.",
      "criteria": [
        "Truncated or fragmentary. Ends mid-thought, or whole sections are missing.",
        "Drafted but unfinished. Complete thoughts, with visible gaps or placeholders.",
        "Complete. An opening, a body and an ending that lands."
      ]
    }
  }
}
Note the shape, because it is easy to get wrong. questions is a map keyed by ids you choose, and your answers come back under those same keys. Choice criteria is a map of option to rubric description. Score criteria is an ordered array of level descriptions.
The single most useful thing we learned: rubrics transformed the score question. Running voice fit with instructions alone, the model returned values of 1.64, 1.58 and 1.95 on a three-level scale, at confidence between 0.37 and 0.45. Those numbers are unusable, and we were ready to drop the question. Adding a described level for every step, exactly as written above, moved the same question to correct answers at confidence 0.94 and above. Same model, same task, same inputs.
If a question is behaving badly, write better criteria before you conclude the model cannot do the job.
Step 2: one call, every question
TypeSafe's speculative fan-out pattern documents that questions in a request are evaluated in parallel, so adding more of them does not typically add latency. Combined with output tokens being free on Jev, asking six questions about a draft costs close to what asking one costs.
That changes how you design the question set. Ask everything you might want, including questions that only matter sometimes, and ignore the irrelevant answers in code.
Here is the handler. It uses Cosmic's TypeScript SDK and calls TypeSafe over HTTP, which is exactly what produced the measured results further down:
import { createBucketClient } from '@cosmicjs/sdk';
import { QUESTIONS } from './questions'; // the question map from Step 1

const cosmic = createBucketClient({
  bucketSlug: process.env.COSMIC_BUCKET_SLUG!,
  readKey: process.env.COSMIC_READ_KEY!,
  writeKey: process.env.COSMIC_WRITE_KEY!,
});

const TYPESAFE_URL = 'https://api.typesafe.ai/v1/systemone';

async function classify(state: string, questions: object) {
  const res = await fetch(TYPESAFE_URL, {
    method: 'POST',
    headers: {
      Authorization: `Bearer ${process.env.TYPESAFE_API_KEY}`,
      'Content-Type': 'application/json',
    },
    body: JSON.stringify({ state, model: 'jev-latest', questions }),
  });

  if (!res.ok) throw new Error(`TypeSafe ${res.status}`);
  return res.json();
}

export async function POST(request: Request) {
  const payload = await request.json();
  const objectId = payload.data?.id;

  const { object } = await cosmic.objects
    .findOne({ id: objectId })
    .props('id,title,slug,metadata');

  const result = await classify(buildState(object), QUESTIONS);
  return Response.json(await writeBack(object, result.answers));
}

// Jev accepts 64k tokens per request across state and all questions,
// and 32k for state plus the longest single question. Long-form bodies
// need trimming before they go in.
function buildState(object) {
  return [
    `TITLE: ${object.title}`,
    object.metadata.markdown_content.slice(0, 40000),
  ].join('\n\n');
}
A response comes back keyed by your question ids, with a usage object carrying input_tokens and output_tokens. TypeSafe also publishes client SDKs that handle retries automatically with their default retry policy. If you call the HTTP API with raw fetch as above, add your own backoff for the documented 429 rate limit responses.
The official JavaScript SDK
Everything above calls the HTTP API directly, which is what produced the numbers further down. For a new integration, TypeSafe's official JavaScript SDK is the better starting point. It is typed end to end, and it handles retries with a default retry policy that the raw fetch above does not have.
npm install @typesafe-ai/sdk@0.6.0
Pin the version deliberately. The package is new: v0.5.7 was the initial public release on September 11, 2026, and v0.6.0 on September 15, 2026 shipped a breaking change to how score criteria are declared (changelog, read September 21, 2026). An unpinned install on a package moving at that speed can break quietly.
import { choice, TypeSafeClient } from '@typesafe-ai/sdk';

// Reads TYPESAFE_API_KEY from the environment.
const client = new TypeSafeClient();

const { answers } = await client.systemOne({
  state: buildState(object),
  questions: {
    property: choice(PROPERTIES),
  },
});

// Answers are typed off the question map you passed in.
const property = answers.property.choice;
Two things to know before you port. Questions are declared with the SDK's typed helpers rather than hand-written JSON, so the rubric from Step 1 gets rebuilt in code and the answers come back typed instead of any. And this snippet follows the documented quickstart (JavaScript SDK reference, read September 21, 2026) without us executing it. The measured results in this post came from the raw HTTP calls above.
Step 3: gate on confidence
This is where classification becomes a workflow. Choice and Score answers carry a confidence value derived from the probability distribution. Above your threshold, act automatically. Below it, hand the draft to a person.
const GATES = {
  property: 0.80,
  content_type: 0.60,
  unverified_claim: 0.80,
};

function route(answers) {
  const needsHuman: string[] = [];

  if (answers.property.confidence < GATES.property) {
    needsHuman.push(
      `Property unclear: ${Object.entries(answers.property.probabilities)
        .filter(([, p]) => p > 0.1)
        .map(([k, p]) => `${k} ${p}`)
        .join(', ')}`
    );
  }

  if (answers.content_type.confidence < GATES.content_type) {
    needsHuman.push(`Content type unclear: ${answers.content_type.choice}`);
  }

  if (answers.unverified_claim.noul >= GATES.unverified_claim) {
    needsHuman.push('Possible unsourced factual claim');
  }

  return { needsHuman, property: answers.property.choice };
}
The flagged reasons matter as much as the flag. An editor who sees "cycling 0.78, outdoor gear 0.21" knows exactly what decision is being asked of them, and can make it in two seconds.
Step 4: write the answer back
The result lands on the Cosmic object, so the queue an editor opens is already organised:
async function writeBack(object, answers) {
  const { needsHuman, property } = route(answers);

  await cosmic.objects.updateOne(object.id, {
    metadata: {
      property,
      voice_score: answers.voice_fit.score,
      triage_status: needsHuman.length ? 'needs_review' : 'auto_filed',
      triage_notes: needsHuman.join(' | '),
    },
  });

  return { needsHuman, property };
}
The object stays in draft. Nothing here publishes anything, and the human approval step is untouched.
What we measured
We built a corpus of 18 drafts across 13 fictional properties and five content types, with defects deliberately seeded on known labels so there was something real to score against. Two of the thirteen properties were newsletter microsites that overlap their parent titles, included specifically to make routing harder. Every draft went through one request carrying the full question set: 18 calls, 102 individual judgments, all HTTP 200.
Property routing: 18 of 18 correct. Twelve came back at confidence 0.95 or above, including both newsletter traps. The finance newsletter resolved to the newsletter over its parent title at 0.84 against 0.16. The food newsletter resolved at 0.98 against 0.02.
With the gate at 0.80, 16 of 18 auto-filed with zero incorrect auto-files, and 2 routed to a human. Both of those were genuinely ambiguous:
-
A fell-running shoe review: cycling title 0.78, outdoor title 0.21.
-
A festival food guide: events title 0.46, food title 0.39, food newsletter 0.15, confidence 0.41.
Those are exactly the two a human should see.
Voice fit: 18 of 18 correct, confidence 0.71 or above throughout. An affiliate-spam draft scored 0.00 at confidence 1.00. This is the question that was unusable before rubrics.
Content type: 13 of 18 correct, and every single disagreement arrived below 0.55 confidence. Set that gate at 0.60 and everything passing the gate was right. As a demonstration of confidence gating, this is cleaner than the routing result, because the model reliably flagged its own errors.
Undisclosed promotion: 12 of 12. A sponsored hotel review that discloses the sponsorship in its first line scored 0.05. An undisclosed affiliate roundup scored 0.94. We dropped this question from the last batch to keep payloads small, so the sample is 12 drafts rather than 18.
Where it was weak
Publishing only the wins would make this useless to you, so here are the three limitations we hit.
Confidence catches genre ambiguity and misses topical overlap. We built a batch specifically to break routing, using drafts that legitimately belong to two titles. It hedged on two and answered confidently on four where a second title had a real claim. An electric-vehicle charger payback analysis, which is half personal finance, returned its energy title at confidence 1.00 with the finance title at exactly 0. Do not use these probabilities to find cross-posting candidates. They answer "which one" and not "how many."
The unsourced-claim question tracks claim density more than sourcing. Across twelve clean drafts it ranged from 0.11 to 0.73. A pure-opinion column containing no factual claims at all scored 0.11, while a fully sourced council report scored 0.59. Separation still held: every seeded-defect draft landed between 0.88 and 0.99, every clean draft stayed at or below 0.73, and a 0.80 gate was correct on all 18. Gate on the separation you observe in your own corpus rather than trusting the absolute value.
Structural completeness was the least reliable. It caught a deliberately truncated guide at 0.03 with confidence 0.97, and it returned confidence 0.00 twice on drafts that are complete and simply end on a short line. Two zero-confidence outputs in 18 is worth knowing before you gate anything important on it.
TypeSafe publishes a jaggedness page for the model, which is an honest signal from a vendor and a reminder to measure on your own content before trusting any question in production.
What it costs
Jev is priced at $0.042 per million input tokens with output tokens free (TypeSafe models, read September 20, 2026). Our run consumed 22,416 input tokens across 18 calls and returned 4,656 output tokens that were not billed.
That is $0.00094 for the whole corpus, roughly $0.000052 per draft, or about 19,000 classified drafts per dollar. Cost is not the constraint on this design. Treat these figures as an illustration from one small run rather than a benchmark.
Running it without webhooks
Webhooks on Cosmic are a $99/month per-project add-on, or $199/month bundled with Localization, Revision History and Automatic Backups (Cosmic pricing, read September 20, 2026). You do not need them to try this.
Poll for untriaged drafts on a schedule instead:
const { objects } = await cosmic.objects
  .find({ type: 'articles', status: 'draft', 'metadata.triage_status': '' })
  .props('id,title,metadata')
  .limit(25);

for (const object of objects) {
  const result = await classify(buildState(object), QUESTIONS);
  await writeBack(object, result.answers);
}
Same classification, same write-back, no add-on required. Move to webhooks when the latency starts to bother you.
Where this leaves the review queue
The editor still approves everything. What changed is what they open: a queue where most drafts are already filed against the right property, scored for voice, and where the handful carrying a possible unsourced claim are at the top with the reason attached.
For a team running five to twenty properties, that difference decides whether draft-only publishing is a policy you can hold or one you quietly abandon.
Cosmic gives you the content model, the draft state, the roles and the API to build this. Start free, read the API and SDK docs, or book a walkthrough if you want to talk through the architecture for your own properties.
Teams running this across many properties at once are who the Cosmic Workspace plans are built for: several projects, one team, one bill.
If you are connecting AI tools to your content more broadly, the Cosmic MCP server is the other half of this story.