Claude Sonnet 5 vs Opus 5: A Real-World Comparison (2026)
Tony Spiro
July 30, 2026
Updated September 3, 2026
Anthropic shipped Claude Sonnet 5 on June 30, 2026 and Claude Opus 5 on July 24, 2026. Both are excellent. The expensive mistake is picking one, wiring it into every code path, and then either overpaying on trivial work or under-resourcing the work that actually matters.
This is the practical breakdown: what each model is measurably good at, what the same job costs on each once you account for tokenization, and a routing rule you can ship this week.
The short answer
| Your workload | Use | Why |
|---|---|---|
| Content generation, summarization, chat, classification, tagging | Sonnet 5 | Highest quality per dollar. This is the volume tier. |
| Day-to-day coding, refactors, test writing, PR review | Sonnet 5 | 72.7% on SWE-bench Verified, a 10.4 point jump over Sonnet 4.6. |
| Long autonomous agent runs with tool calls | Opus 5 | Anthropic reports it ranked first on Zapier's AutomationBench for end-to-end task completion. |
| Architecture decisions, ambiguous multi-step problems, novel reasoning | Opus 5 | Self-verification and judgment are the headline improvements. |
| Anything where a wrong answer is expensive to unwind | Opus 5 | Lowest misaligned-behavior score of Anthropic's recent releases at 2.3. |
| High-volume production traffic on a budget | Sonnet 5 | It is the default on Claude Free and Pro for a reason. |
If you want one sentence to take away: run Sonnet 5 by default and escalate to Opus 5 on the specific paths where judgment matters more than throughput.
Now make that decision cheap to change. Anthropic shipped two frontier models in 25 days. If the model name lives in your source files, every release becomes a pull request and a deploy. Jump to the routing pattern that keeps model config out of your codebase, or see how Cosmic runs these models in production.
Run the model you just picked against real content. A routing table only earns its keep once the model has real material to work on: your posts, your product copy, your docs. Cosmic gives agents a structured content layer they can read and write through a REST API, a TypeScript SDK, and a per-bucket MCP server, with read and write issued as separate keys, so a high-volume Sonnet 5 job and an Opus 5 escalation path can hold different permissions on the same content.
The models and tools you just read about keep changing every few months. Cosmic gives you a model-agnostic, API-first content backend that stays stable underneath them: structured objects, a TypeScript SDK, scoped API keys, and built-in analytics. See how it works with AI agents or start free, no credit card required.
What the benchmarks actually say
There is a wrinkle worth knowing before you compare scores. Anthropic evaluated these two models on different suites, so there is no clean head-to-head table, and anyone who publishes one has filled in gaps with guesses.
Here is what was actually published for Sonnet 5:
| Benchmark | Sonnet 5 | Sonnet 4.6 | Opus 4.8 |
|---|---|---|---|
| SWE-bench Verified | 72.7% | 62.3% | 79.4% |
| Terminal-bench | 76.1% | 55.4% | not published |
| GPQA Diamond | 78.0% | not published | not published |
| MMMU | 76.3% | not published | not published |
| MathVista | 76.6% | not published | not published |
| CharacterEval | 90.3% | not published | not published |
And here is what was published for Opus 5:
- State of the art on coding and knowledge work, measured on Frontier-Bench and GDPval-AA.
- First place on Zapier's AutomationBench for end-to-end task completion.
- An ARC-AGI 3 score roughly three times the next-best model.
- A misaligned-behavior score of 2.3, the lowest of Anthropic's recent releases.
- Matches Claude Fable 5 on intelligence at approximately half the cost.
- A fast mode that runs about 2.5x quicker.
Notice what is missing: Anthropic did not publish a SWE-bench Verified number for Opus 5. So the honest comparison on classic coding benchmarks is Sonnet 5 at 72.7% against Opus 4.8 at 79.4%, with Opus 5 positioned above Opus 4.8 on the newer agentic and knowledge-work suites. Treat any "Opus 5 scores X% on SWE-bench" claim you find elsewhere as unsourced.
The practical read: Sonnet 5 closed most of the gap to the previous Opus generation on straightforward coding. Opus 5's advantage shows up in long-horizon agent work, self-verification, and problems where the model has to decide what the task even is.
What it actually costs
List prices per million tokens, all verified against Anthropic's pricing page on September 2, 2026:
| Model | Input | Output | Notes |
|---|---|---|---|
| Sonnet 5 | $2 | $10 | Current list price |
| Sonnet 5 | $3 | $15 | Planning scenario only, see the verification note below |
| Opus 5 | $5 | $25 | Same as legacy Opus 4.8, which is still listed at $5 / $25. |
| Fable 5.1 | $10 | $50 | Anthropic's current top tier, for context on what the ceiling costs. |
| Fable 5 | $10 | $50 | Now listed under Anthropic's legacy models, at the same rate as Fable 5.1. |
| Haiku 4.5 | $1 | $5 | The cheap tier, if your task is genuinely simple. |
Verification note, September 2, 2026. Anthropic's pricing page today lists Sonnet 5 at $2 input and $10 output per million tokens, with no end date shown for that rate, and Opus 5 at $5 and $25. An earlier version of this post described the $2/$10 rate as introductory pricing expiring August 31, 2026. That date has now passed and the rate is unchanged, so treat the $3/$15 rows as a planning scenario rather than a scheduled change. Note that $3/$15 is the current listed price of the legacy Sonnet 4.6 and Sonnet 4.5 models, which may be where that figure originated. Also changed since the last pass: Anthropic's top tier is now Claude Fable 5.1 (API ID claude-fable-5-1) at $10/$50, and Fable 5 has moved into the legacy model list at the same rate. Check Anthropic's pricing page before you commit a budget to any of these numbers.
Headline math says Opus 5 costs 2.5x Sonnet 5 at today's $2/$10 rate, and 1.67x in the $3/$15 scenario. Both understate Sonnet 5's real cost, because Sonnet 5 ships a new tokenizer that counts the same text as 1.0x to 1.35x more tokens. You pay per token, not per word, so that inflation lands on your invoice.
Work a concrete example. Take a job that a baseline tokenizer counts as 1,000,000 input tokens and 200,000 output tokens:
| Scenario | Input cost | Output cost | Total | Opus 5 premium |
|---|---|---|---|---|
| Opus 5 | $5.00 | $5.00 | $10.00 | baseline |
| Sonnet 5 at $3/$15, no inflation | $3.00 | $3.00 | $6.00 | 1.67x |
| Sonnet 5 at $3/$15, 1.35x inflation | $4.05 | $4.05 | $8.10 | 1.23x |
| Sonnet 5 at $2/$10, no inflation | $2.00 | $2.00 | $4.00 | 2.50x |
| Sonnet 5 at $2/$10, 1.35x inflation | $2.70 | $2.70 | $5.40 | 1.85x |
That 1.23x row is the one that should change your thinking. On text-heavy workloads that tokenize badly, in the higher-price scenario, Opus 5 costs about 23% more than Sonnet 5 rather than 67% more. If judgment quality matters on that path at all, a 23% premium is easy to justify.
Two caveats so you use this honestly. The inflation range is 1.0x to 1.35x depending on your content, and where you land is an empirical question about your own data. And because the $3/$15 figure is a scenario rather than a published rate, rebuild any cost model against Anthropic's live pricing page before you rely on it. Run 1,000 real requests through both models, compare your actual billed token counts, and decide from your numbers instead of this table.
A routing rule you can ship
Most teams do not need a clever classifier. A static route based on task type captures nearly all of the savings:
- Default to Sonnet 5. Content, chat, summaries, tagging, ordinary code changes.
- Escalate to Opus 5 on three triggers: the task requires more than roughly ten tool calls, the task is architectural or ambiguous, or a wrong answer is expensive to reverse.
- Escalate on retry. If Sonnet 5's output fails validation twice, retry once on Opus 5 instead of a third time on Sonnet 5. This is the highest-return rule on the list and it takes about six lines of code.
- Never hardcode the model name. Anthropic shipped two frontier models in 25 days, and the top tier moved from Fable 5 to Fable 5.1 since this post was first published. Whatever you pin today will be stale within a quarter. When Opus 5 shipped, we made it available in Cosmic the same week and no customer had to redeploy to get it.
Before you ship trigger 1: decide what the agent can reach
Escalation trigger 1 has a security question attached to it. "More than roughly ten tool calls" describes a model running a loop against real systems, and at that point the credential the agent holds is what bounds your blast radius. Opus 5's 2.3 misaligned-behavior score is a good reason to prefer it on those paths. Behavior scores do not function as access controls.
If one of those systems is your content, Cosmic's MCP server gives the agent a bounded surface: a per-bucket endpoint, and read and write issued as two separate keys. Hand a client the read key and it gets the read tools only, so a create or delete call fails at the API boundary instead of depending on the model or your system prompt holding up. Point it at a sandbox bucket with a write key when you want it drafting freely, and keep production read-only. We wrote up the four controls you can verify yourself, plus the two we do not ship yet, in AI agent write access: the 4 real controls you get with your CMS.
Want to try the setup instead of reading about it? There is a 10-minute lesson that walks through this exact configuration: Connect Cosmic to Cursor and Claude Code with MCP. It covers the MCP config block for both editors and finishes with a step you run against your own bucket, so you can watch the read-only key refuse a write rather than take our word for it. The lesson is free to read and needs no account until the last step.
Point four is where most of the long-term pain lives. If your model identifiers are compiled into your application, every model release becomes a pull request, a review, and a deploy.
Keep model config out of your codebase
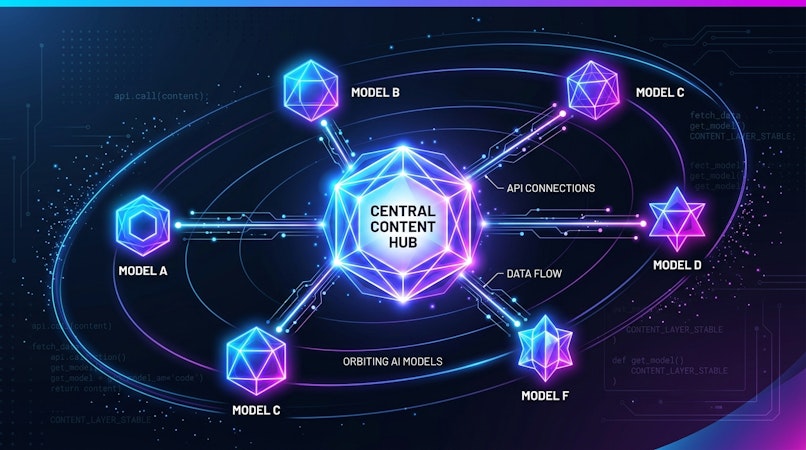
Store your routing configuration as content instead. Then swapping Sonnet 5 for Sonnet 5.1 is a field edit that takes effect immediately, with no rebuild.
Install the SDK:
npm install @cosmicjs/sdk
Define the routing table as an object in Cosmic and read it at runtime:
import { createBucketClient } from '@cosmicjs/sdk';

const cosmic = createBucketClient({
  bucketSlug: process.env.COSMIC_BUCKET_SLUG!,
  readKey: process.env.COSMIC_READ_KEY!,
});

type ModelRoute = {
  default_model: string;
  escalation_model: string;
  escalate_after_failures: number;
};

export async function getModelRoute(): Promise<ModelRoute> {
  const { object } = await cosmic.objects
    .findOne({ type: 'model-config', slug: 'production' })
    .props('metadata')
    .depth(0);

  return object.metadata as ModelRoute;
}
Use it at the call site:
const route = await getModelRoute();

let model = route.default_model;        // "claude-sonnet-5"
if (isArchitectural(task) || failures >= route.escalate_after_failures) {
  model = route.escalation_model;       // "claude-opus-5"
}

const result = await runTask({ model, task });
When the next model lands, a non-engineer updates one field in the dashboard and production picks it up. No deploy, no pull request, no engineer in the loop. Cosmic exposes this over a REST API and the TypeScript SDK, so the same config is readable from any framework or runtime you use. If that runtime is a React or Next.js app, our React and Next.js CMS guide covers the tradeoffs specific to that stack, and React CMS walks through the data-fetching patterns. If you want to see the pattern working end to end before you build it, Cosmic's AI features run on exactly this architecture.
This is the same argument we make in why your AI stack should be model-agnostic: the release cadence is now fast enough that hardcoding any vendor's model name is a maintenance liability. For the previous generation's version of this decision, see Sonnet 4.5 vs Opus 4.5. If you are choosing the platform underneath all of this, our best headless CMS for 2026 breakdown covers the tradeoffs.
Frequently asked questions
Is Opus 5 better than Sonnet 5?
On ambiguous reasoning, long autonomous agent runs, and self-verification, yes. On cost per acceptable output for high-volume tasks, Sonnet 5 wins clearly. They are built for different jobs.
What does Claude Sonnet 5 cost?
$2 per million input tokens and $10 per million output tokens, verified against Anthropic's pricing page on September 2, 2026. That page shows no end date for the rate. The previously rumored increase to $3 and $15 has not appeared, so check Anthropic's pricing directly before budgeting.
What does Claude Opus 5 cost?
$5 per million input tokens and $25 per million output tokens, verified September 2, 2026. The same rate as legacy Opus 4.8.
What is Anthropic's most capable model right now?
Claude Fable 5.1 (claude-fable-5-1), listed at $10 per million input tokens and $50 per million output tokens, verified September 2, 2026. Anthropic positions it for demanding reasoning and long-horizon agentic work. Fable 5 is now in the legacy model list at the same rate.
Did Anthropic publish a SWE-bench Verified score for Opus 5?
No. Sonnet 5 scored 72.7% and Opus 4.8 scored 79.4%. Opus 5's published results cover Frontier-Bench, GDPval-AA, Zapier AutomationBench, and ARC-AGI 3.
Which Claude model should I use for coding?
Sonnet 5 for the majority of day-to-day work. Escalate to Opus 5 for architecture, cross-cutting refactors, and anything where you cannot cheaply verify the result. See our deeper breakdown on choosing between Sonnet and Opus.
Why do my Sonnet 5 token counts look higher than expected?
Sonnet 5 uses a new tokenizer that counts the same text as 1.0x to 1.35x more tokens than the previous generation. Compare billed tokens, not word counts.
How do I stop an agent from damaging my content during a long run?
Scope the credential rather than trusting the prompt. Cosmic issues read and write as separate per-bucket keys, so a read-only client physically cannot create, update, or delete. The MCP server page covers setup and the write-access controls post covers what each control does and does not cover.
Can I switch models without redeploying my app?
Yes, if the model identifier lives in your content layer rather than your source. Store it as a field in Cosmic, read it at runtime through the TypeScript SDK, and a dashboard edit takes effect on the next request. Cosmic's AI features are built this way.
Build on infrastructure that outlives the model
Anthropic shipped two frontier models in under a month, and the top tier has already moved from Fable 5 to Fable 5.1. The teams handling that well are the ones that never put a model name in a source file.
Cosmic is an AI-powered headless CMS where your content and your configuration both live behind a REST API and a TypeScript SDK. Model choice becomes a content decision, editable by anyone on your team, live in production the moment it is saved. See how it works.
Start free on the Free plan with 1 Bucket, 2 team members, and 1,000 Objects. No credit card required. If you want to talk through a specific architecture, book a time to talk.
Last verified: September 2, 2026. Anthropic model names and list pricing for Sonnet 5, Opus 5, Fable 5.1, Fable 5, Haiku 4.5, and the legacy models were re-checked against Anthropic's pricing page and the models overview in this pass. This pass corrected the top-tier model: Fable 5.1 is now current and Fable 5 has moved to the legacy list. Benchmark figures come from Anthropic's Sonnet 5 and Opus 5 release materials and were not re-verified in this pass.
September 3, 2026 update: the mid-article call to action was moved into a tracked content block so its clicks register in analytics. No pricing, benchmark, model name, or other third-party figure was changed or re-verified in that pass; September 2, 2026 remains the verification date for every vendor claim above.
Give your AI agents a content backend they can write to
Structured, versioned content objects, a REST API and TypeScript SDK, and an MCP server your coding agent connects to directly. The Free plan includes 1 Bucket, 1,000 Objects, and 1 agent. No credit card required.